Matching-Based Few-Shot Semantic Segmentation Models
Are Interpretable by Design

1University of Bari Aldo Moro, 2Jheronimus Academy of Data Science (JADS), 3Eindhoven University of Technology (TU/e)
NeurIPS 2026
Affinity Explainer Framework

Affinity Explainer computes attribution maps using the matching scores between query and support images in matching-based FSS models. It reveals the specific support regions that most influence the segmentation of the query.

Abstract

Few-Shot Semantic Segmentation (FSS) models achieve strong performance in segmenting novel classes with minimal labeled examples, yet their decision-making processes remain largely opaque. While explainable AI has advanced significantly in standard computer vision tasks, interpretability in FSS remains underexplored despite its critical importance for understanding model behavior and guiding support set selection in data-scarce scenarios.

We argue that matching-based FSS models are interpretable by design: their core similarity computation between support and query features constitutes an inherent attribution mechanism. Our approach, Affinity Explainer (AffEx), makes this intrinsic interpretability explicit by extracting attribution maps directly from matching scores at multiple feature levels, without requiring gradients or external perturbations.

We extend standard interpretability evaluation metrics to the FSS domain and propose additional metrics to better capture the practical utility of explanations in few-shot scenarios. Comprehensive experiments on FSS benchmark datasets demonstrate that AffEx significantly outperforms adapted standard attribution methods, confirming that the matching mechanism itself is the key driver of interpretability. Qualitative analysis reveals structured, coherent attention patterns that align with model architectures and enable effective model diagnosis, laying the groundwork for interpretable FSS research.
Qualitative Results


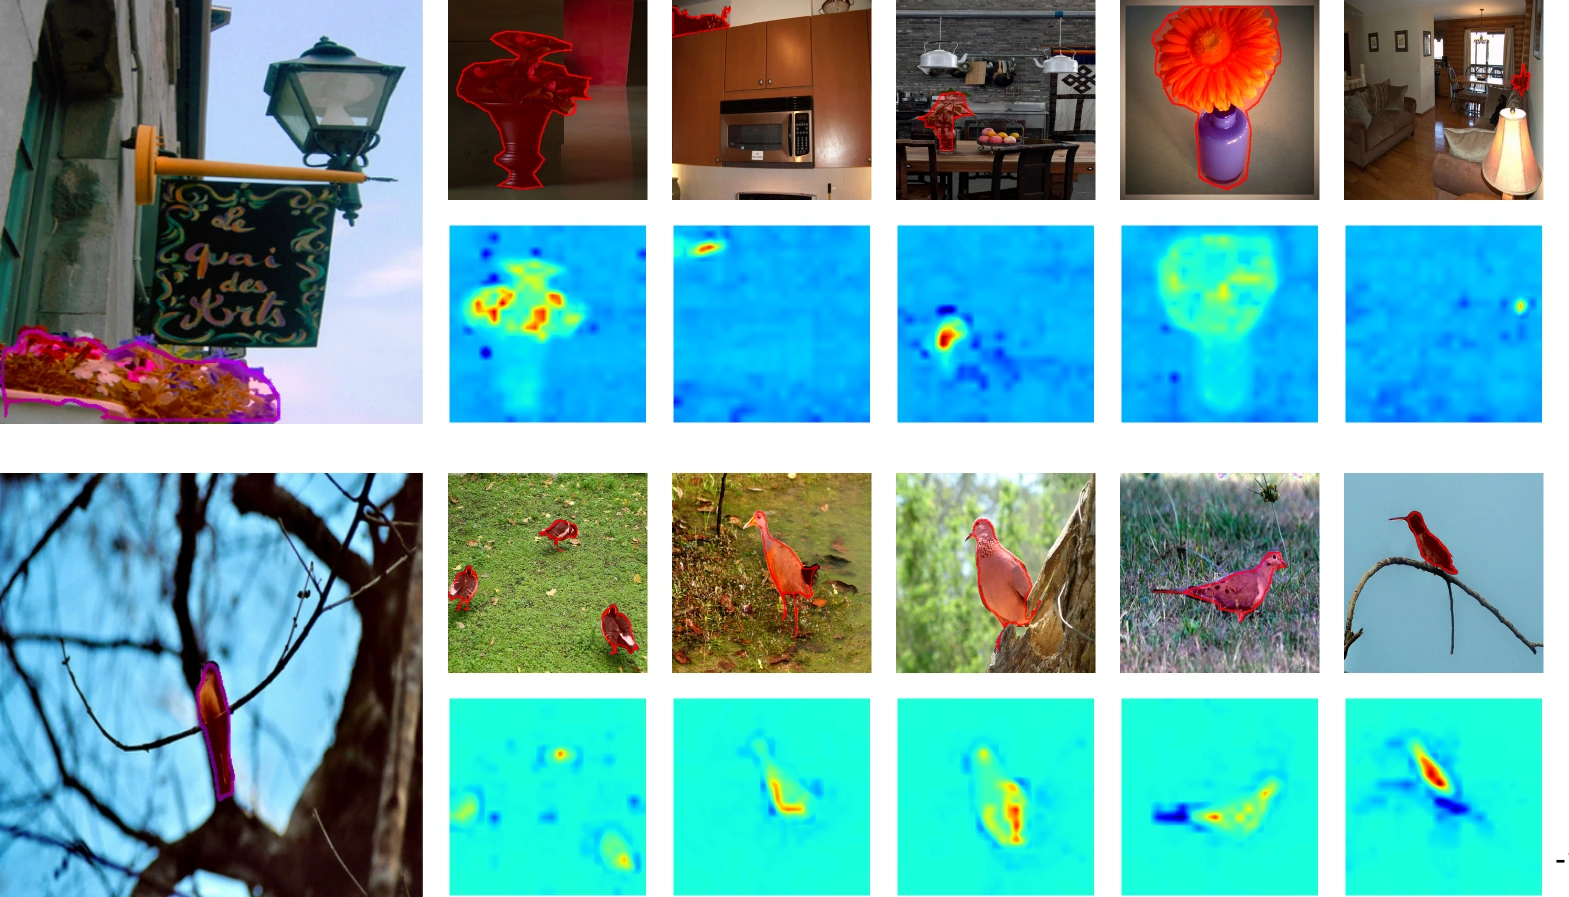
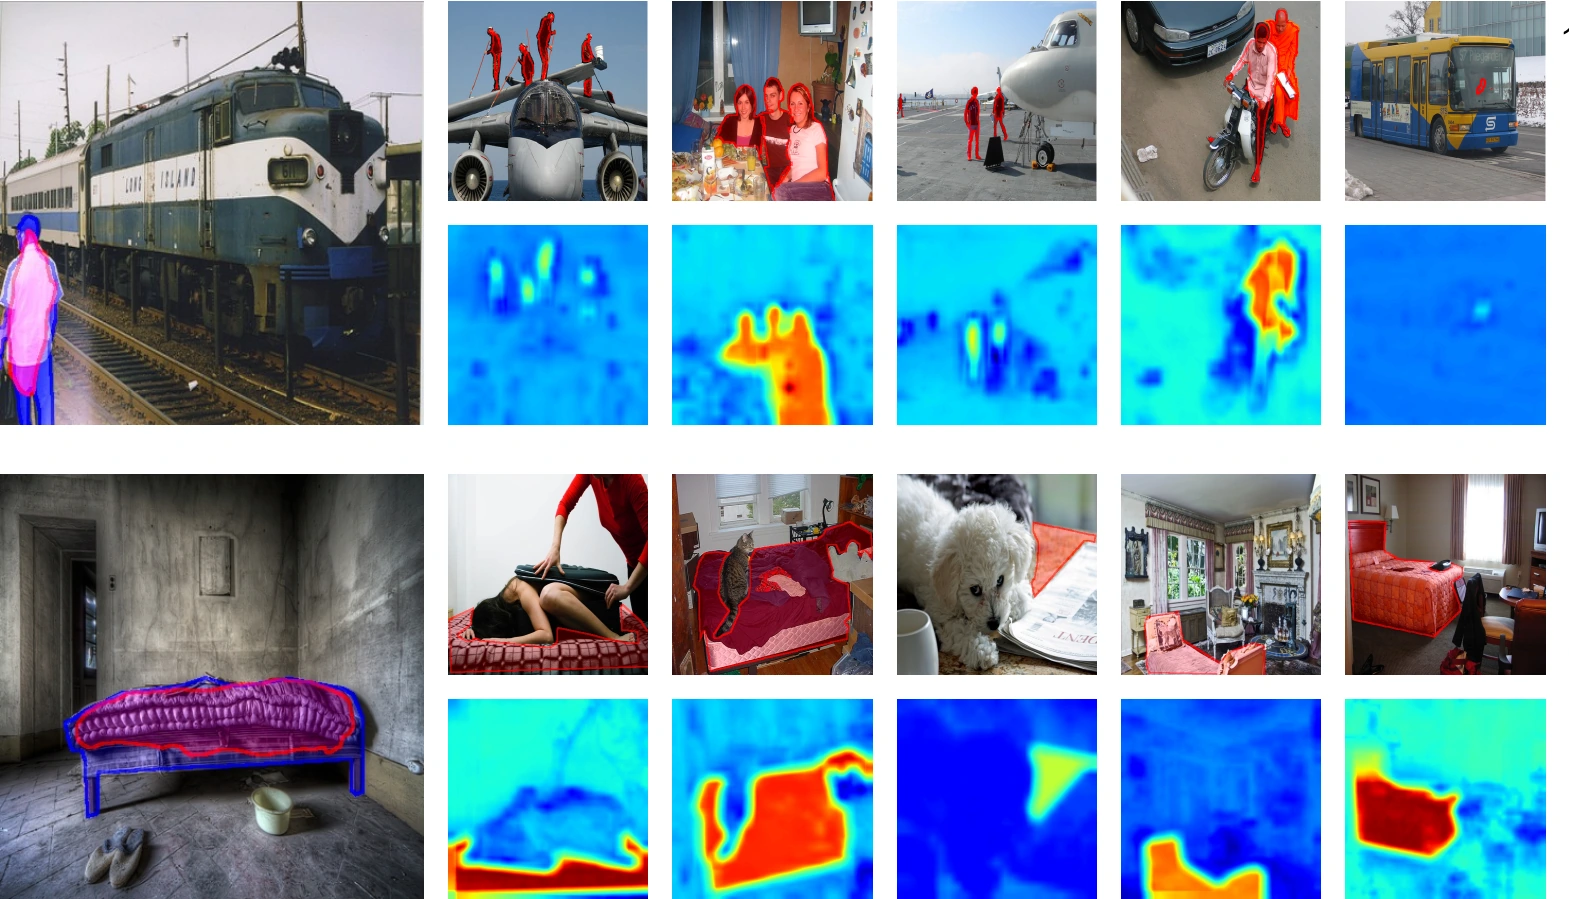
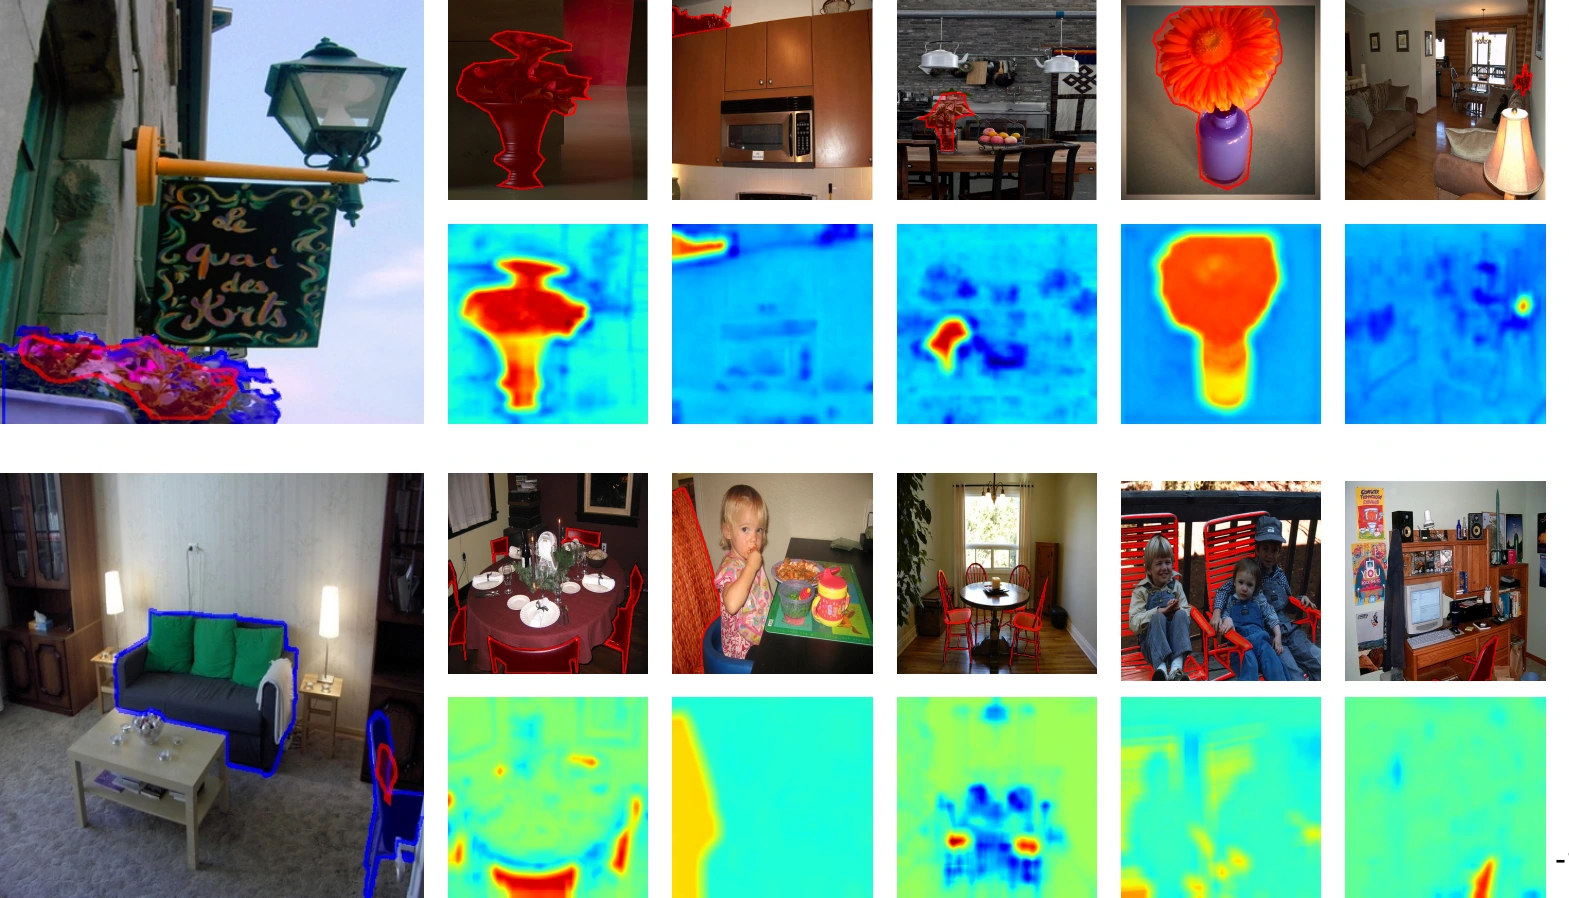
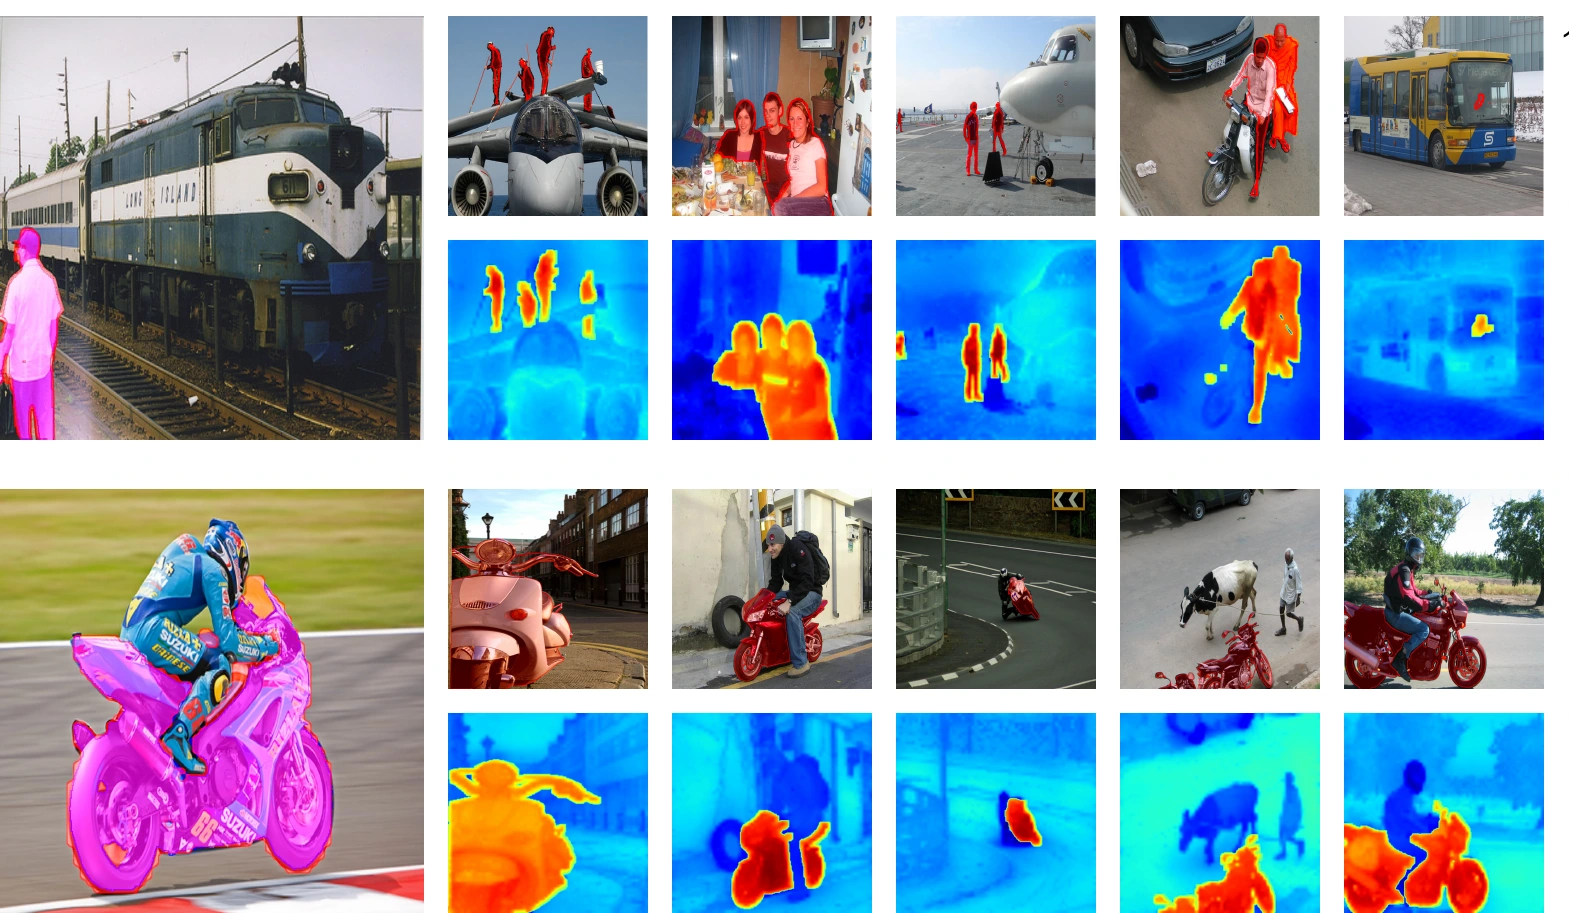
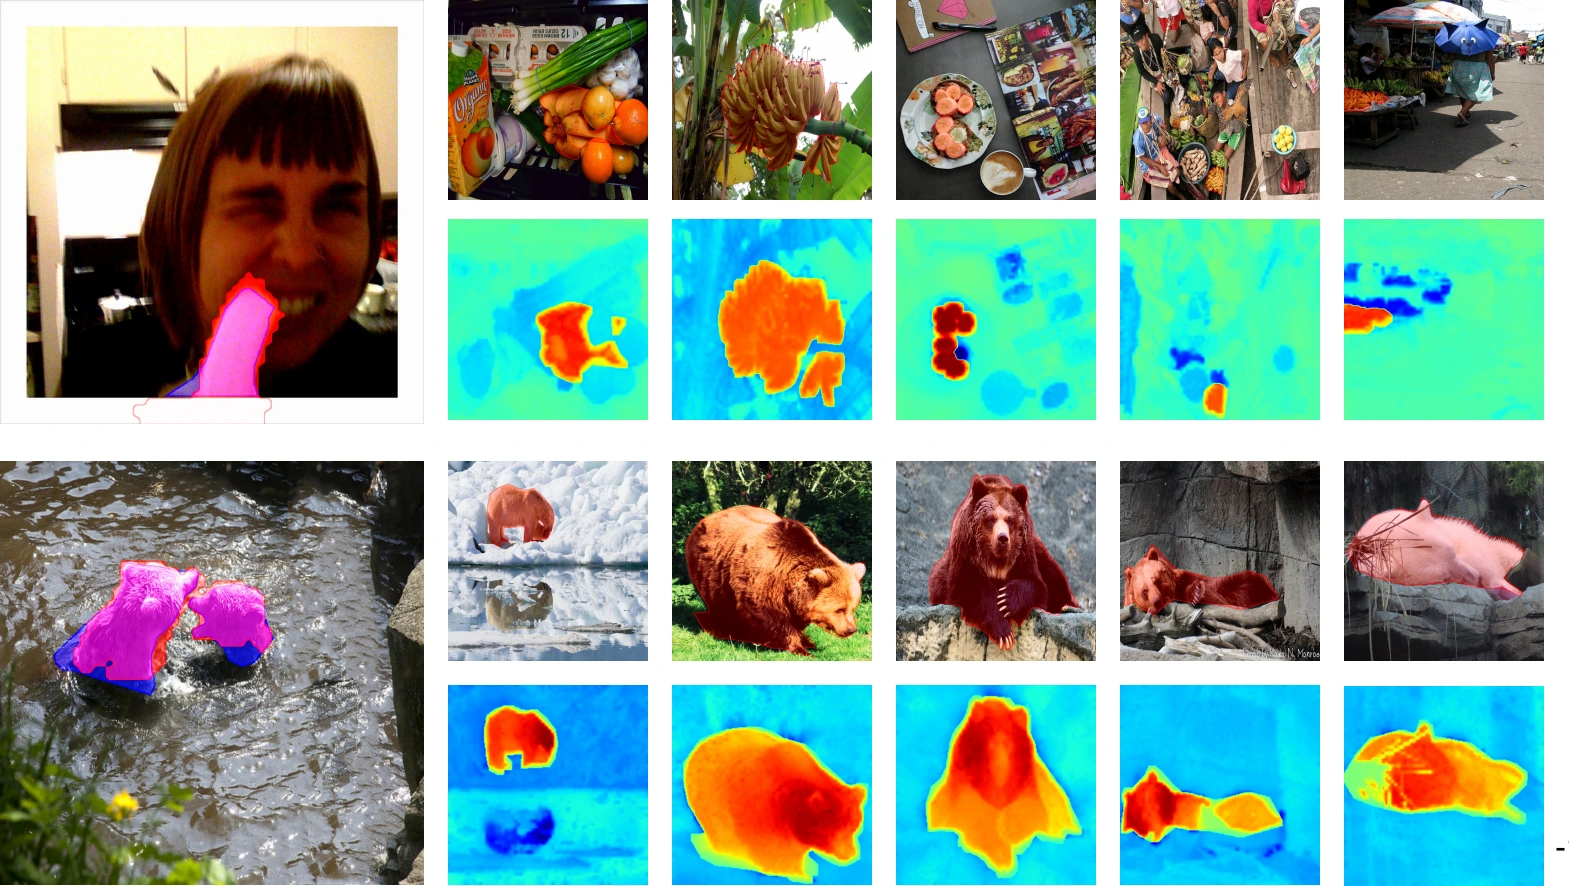
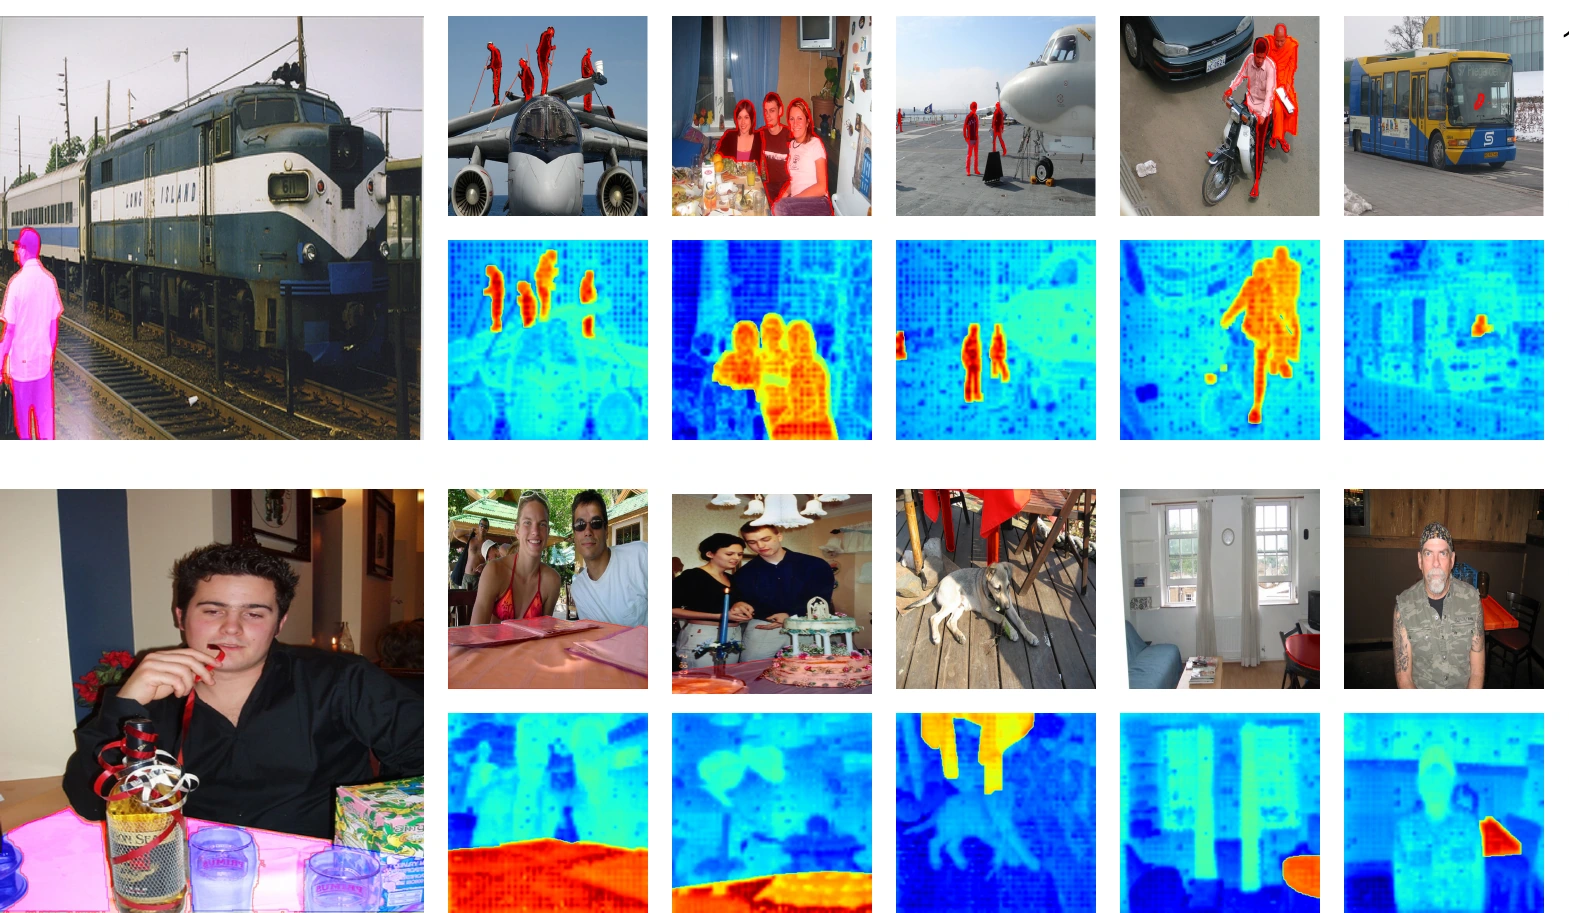
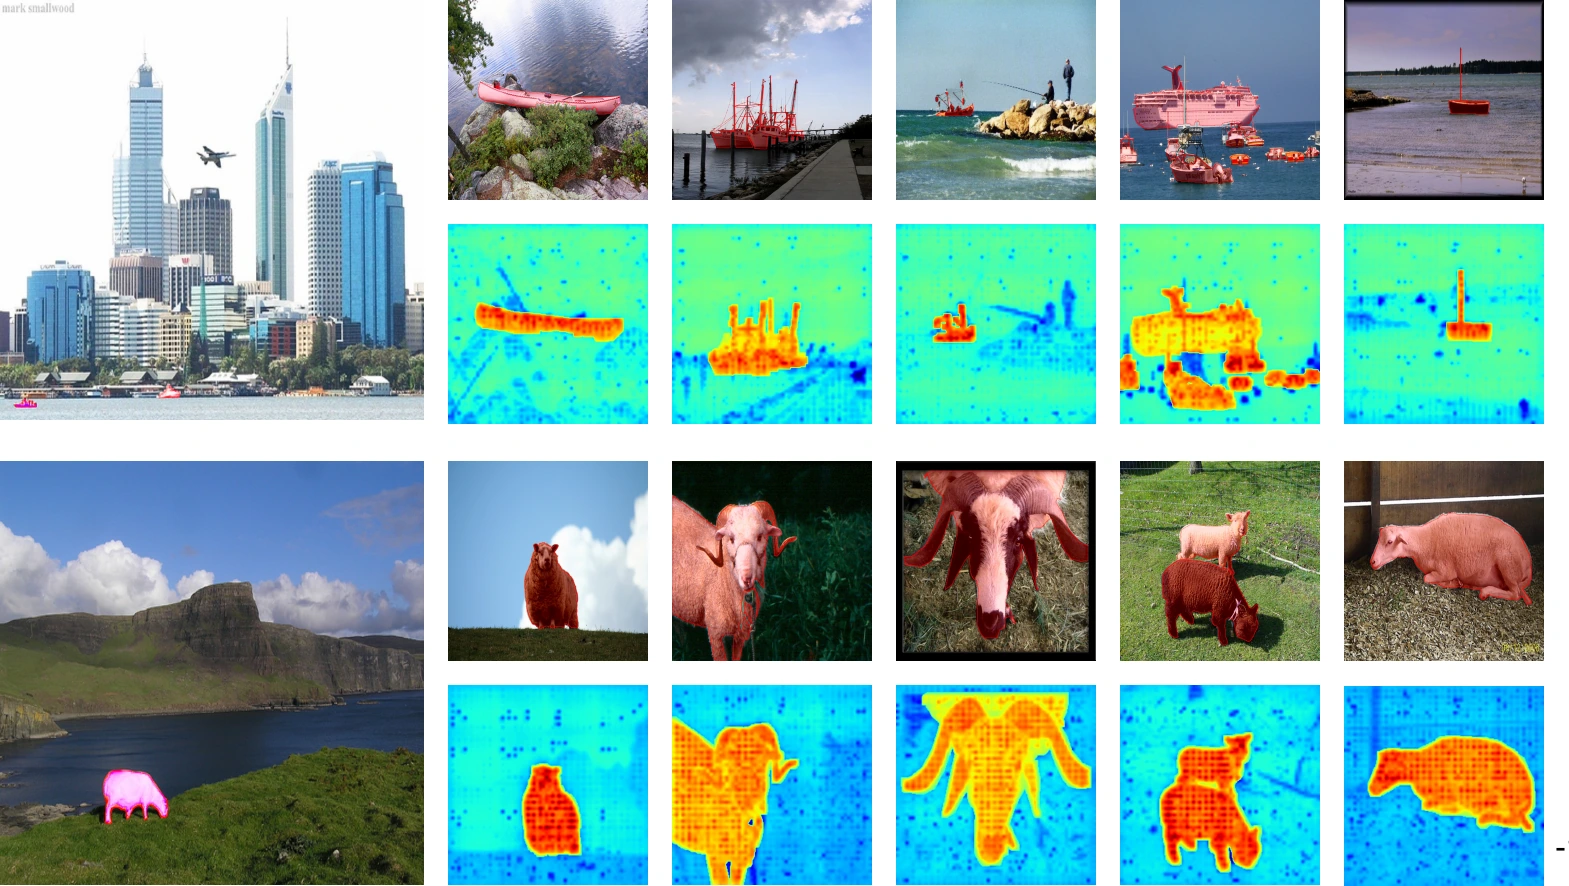
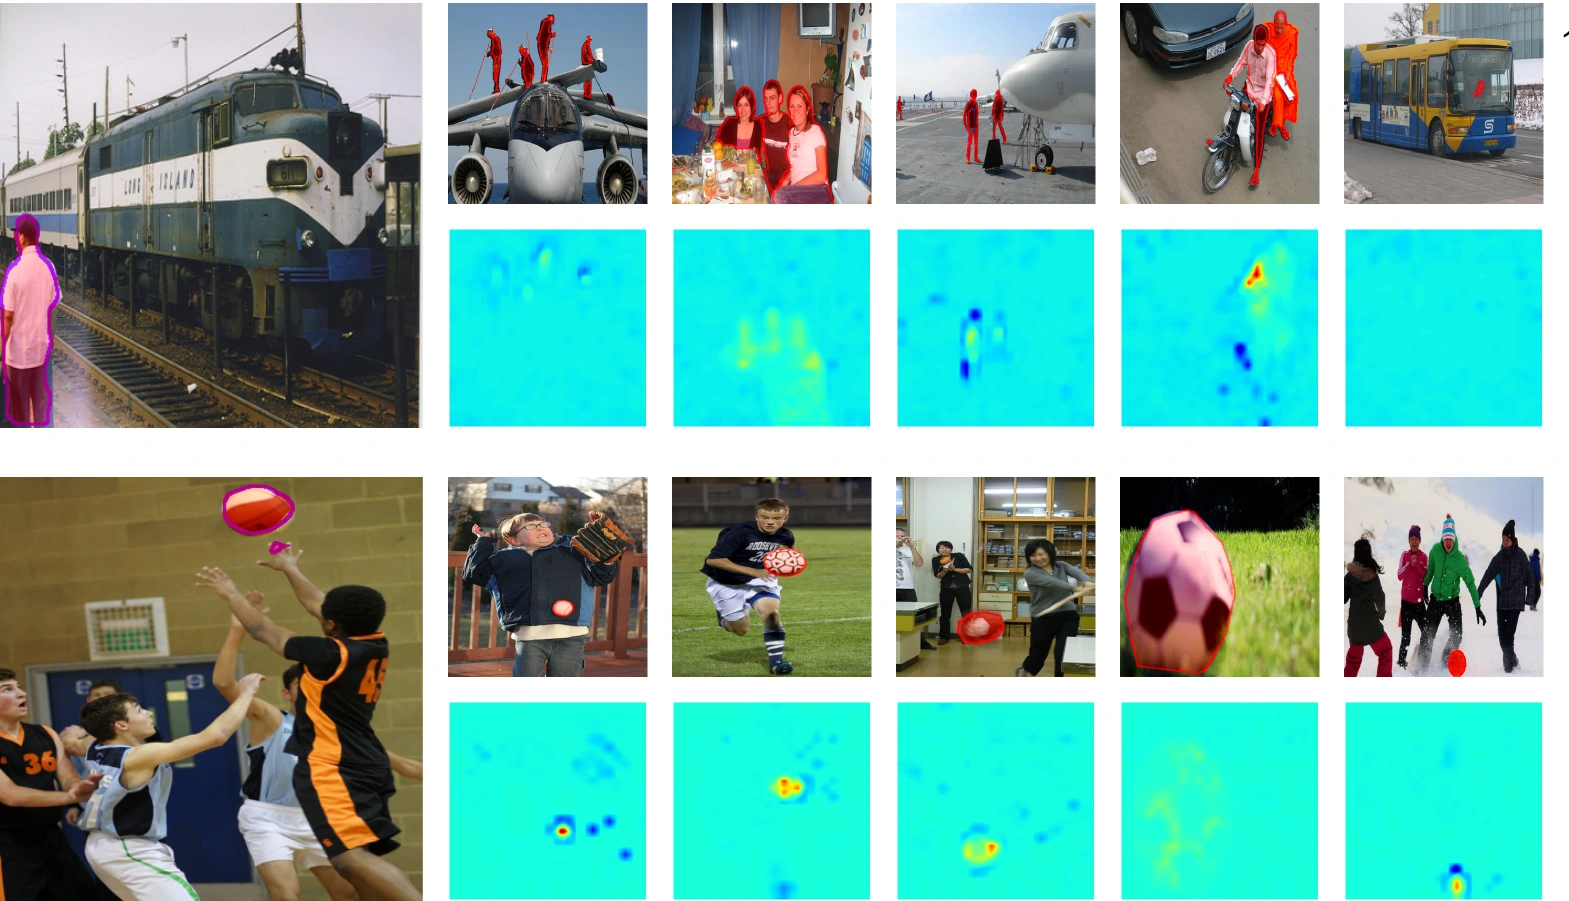
Every support image gets its own attribution map, so it is visible which shot the prediction leaned on and which one contributed nothing. Five-shot episodes from COCO-20i and Pascal-5i, two per slide. The query is on the left with the prediction in red, the ground truth in blue where it differs. In the maps, red marks the support pixels that carry the prediction and blue those that pull against it.


DCAMA attributions over a five-shot support set

DCAMA

DCAMA attributions over a five-shot support set

DCAMA

DMTNet attributions over a five-shot support set

DMTNet

DMTNet attributions over a five-shot support set

DMTNet

INSID3 attributions over a five-shot support set

INSID3

INSID3 attributions over a five-shot support set

INSID3

SANSA attributions over a five-shot support set

SANSA

SANSA attributions over a five-shot support set

SANSA


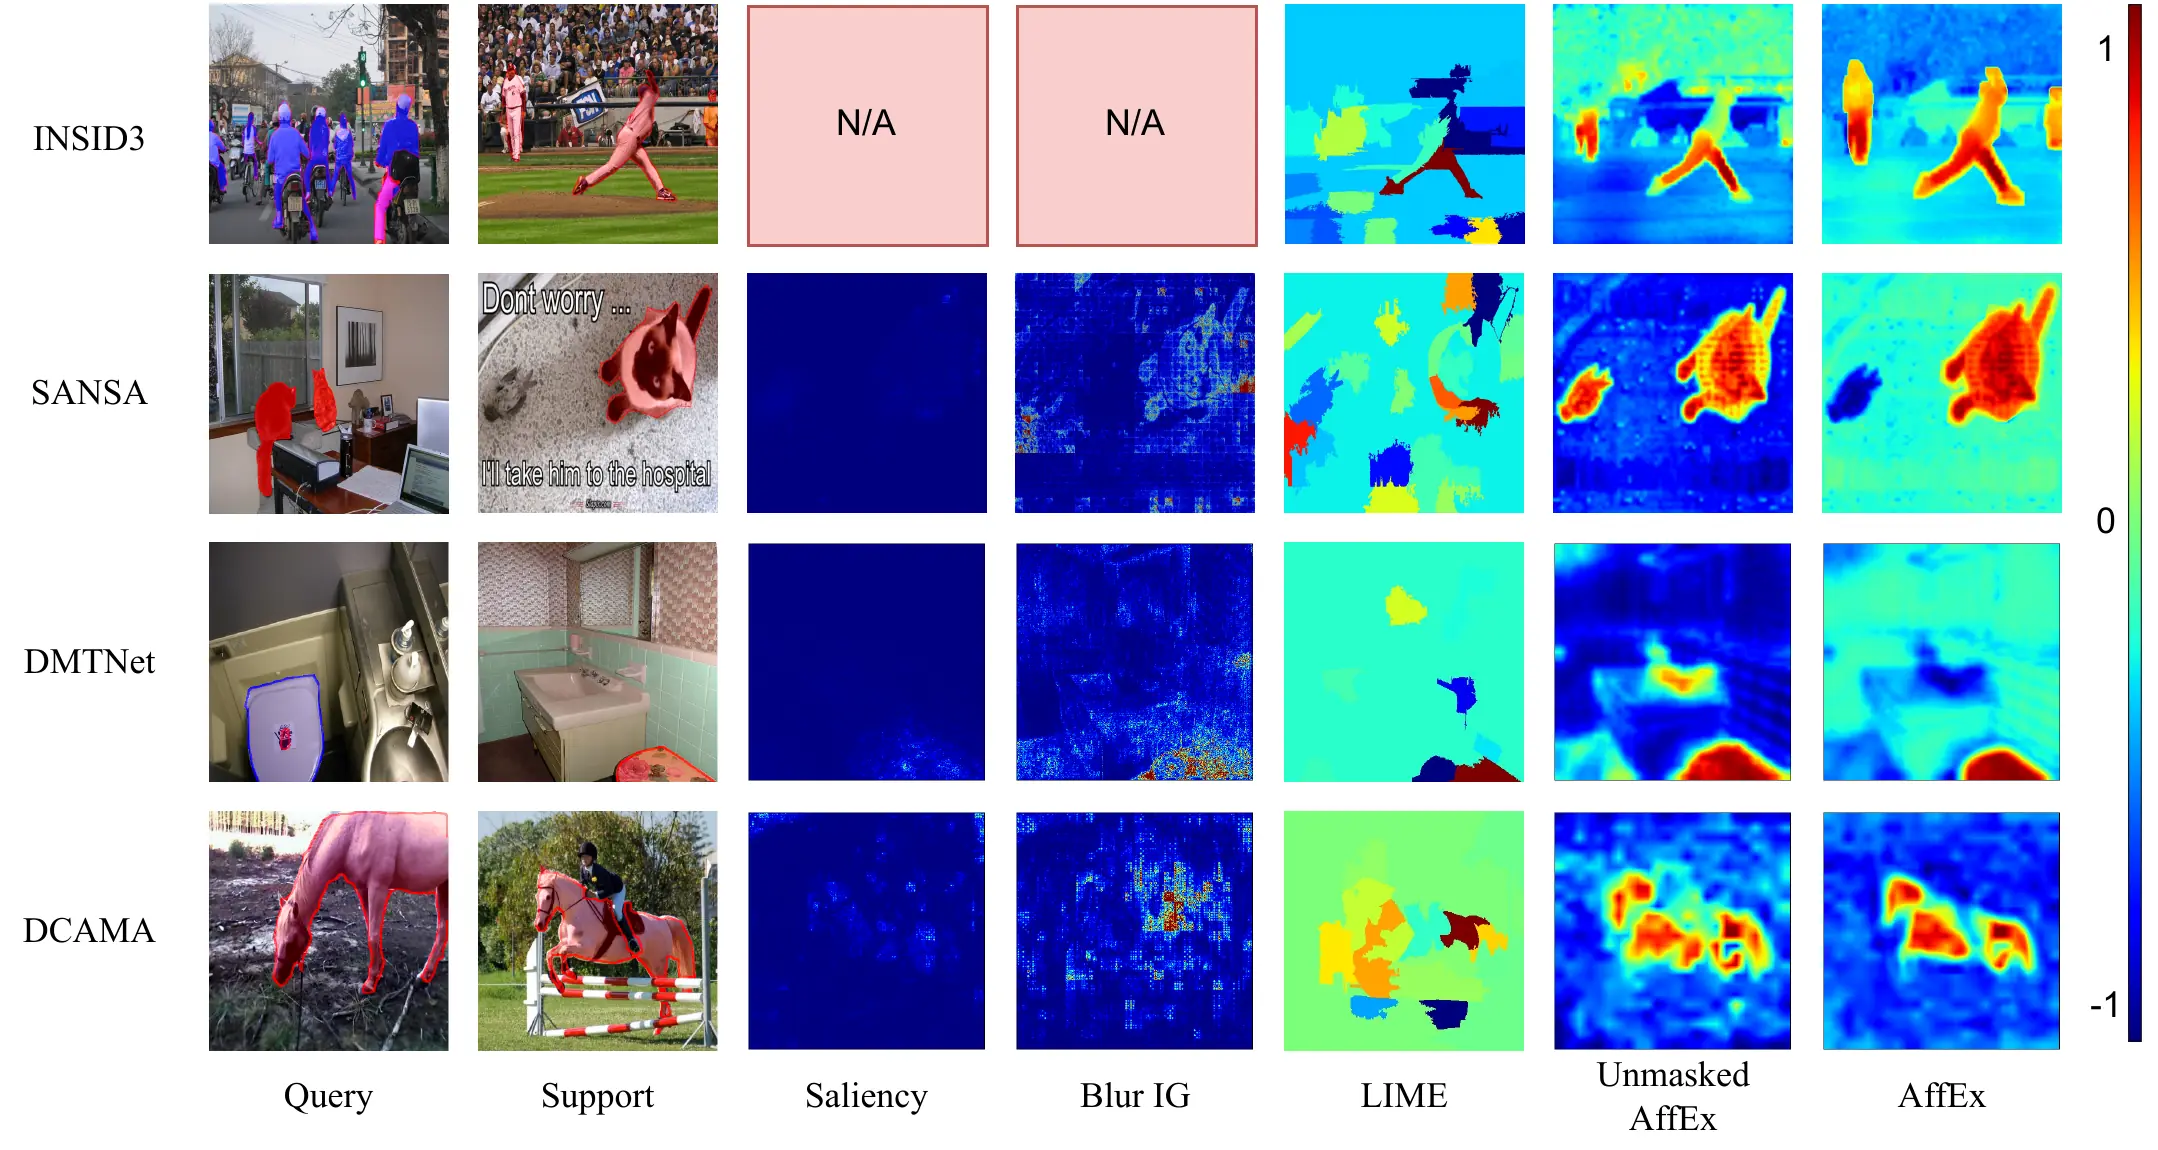
Next to the other attribution methods

One 1-shot episode per model. The gradient methods do not apply to INSID3, whose decision path is not differentiable.


AffEx against the baselines, one episode per model

AffEx Icon Affinity Explainer
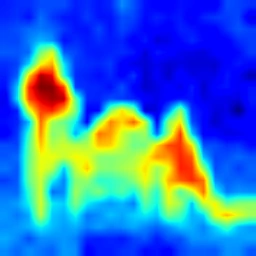
Affinity Explainer is a novel interpretability framework tailored for matching-based Few-Shot Semantic Segmentation (FSS) models. Unlike generic explanation methods (e.g., Grad-CAM) that often struggle with the multi-image inputs of few-shot tasks, AffEx directly leverages the model's internal matching mechanism to reveal how prediction decisions are made.
Core Mechanism

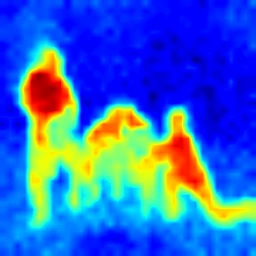
Matching-based models compare query and support features to decide what to segment. AffEx reads the scores that comparison produces and turns them into an attribution over the support pixels, in four steps.

  1. Slice and average: the scores hold every query position against every support position of every shot. AffEx slices them at the region being explained and averages over it, leaving one map per support image.
  2. Softmax: normalised over the whole support set, so the scores read as relative contributions.
  3. Aggregation: one map per feature level, aggregated into one.
  4. Support mask: dilated and smoothed, it sets the sign: positive on the object (red), negative outside it (blue). Without this step, the Unmasked variant.

How an attribution is built

Every panel below is the real output of one 3-shot COCO-20i episode of the class person, with INSID3 as the model.


Query

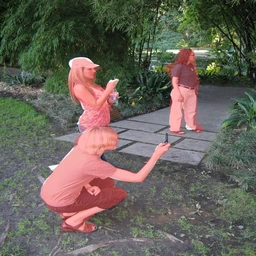
Query image Query with the predicted region in red

the region to explain

Support set

Support image 1 Support image 1 with its mask

shot 1

Support image 2 Support image 2 with its mask

shot 2

Support image 3 Support image 3 with its mask

shot 3

FSS Model

Matching scores

The predicted region
sliced and averaged over the selected region
Level 1, shot 1
Level 2, shot 1
Level 3, shot 1
Level 4, shot 1
shot 1
Level 1, shot 2
Level 2, shot 2
Level 3, shot 2
Level 4, shot 2
shot 2
Level 1, shot 3
Level 2, shot 3
Level 3, shot 3
Level 4, shot 3
shot 3
aggregate
Aggregated attribution, shot 1
Aggregated attribution, shot 2
Aggregated attribution, shot 3
× support mask + inside, − outside
AffEx attribution, shot 1

shot 1carries the most

AffEx attribution, shot 2

shot 2

AffEx attribution, shot 3

shot 3

Diagnosing a wrong prediction

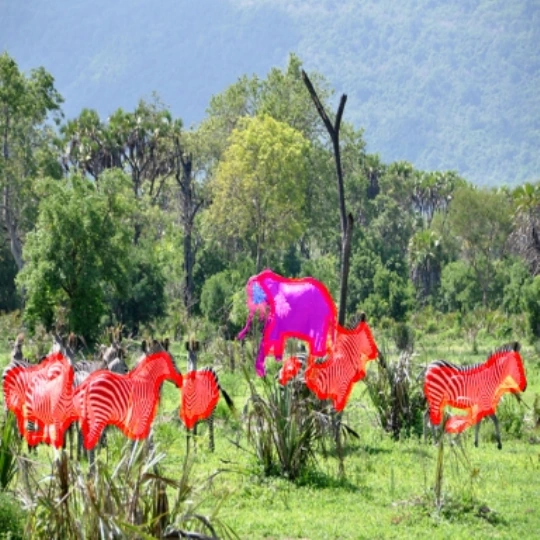
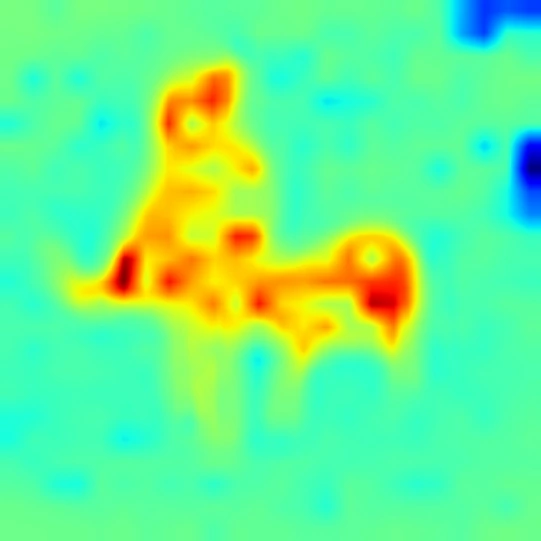
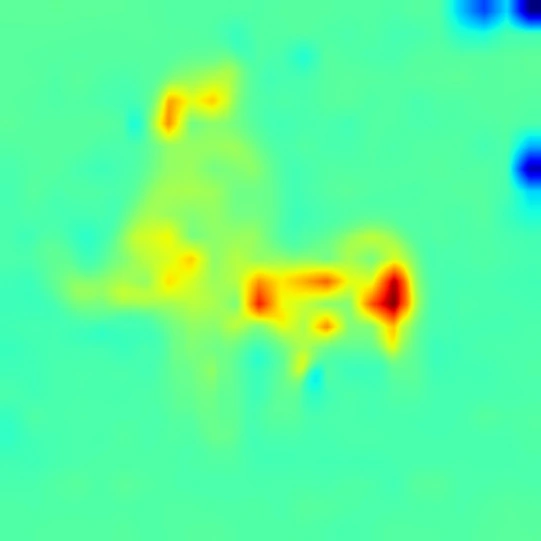
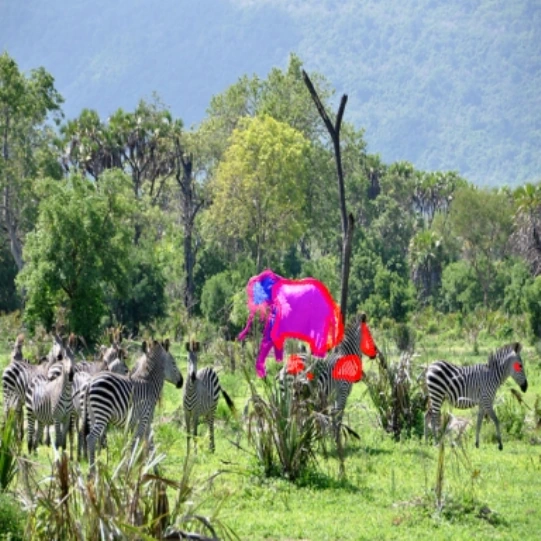
DCAMA is asked for the elephant and returns it, but paints several zebras as well. Accuracy alone says the episode failed; the attribution says why.

The failing prediction: the elephant in magenta, zebras wrongly in red
the prediction
Attribution taken over the predicted region
attribution over the prediction
Attribution taken over the ground truth region
attribution over the ground truth
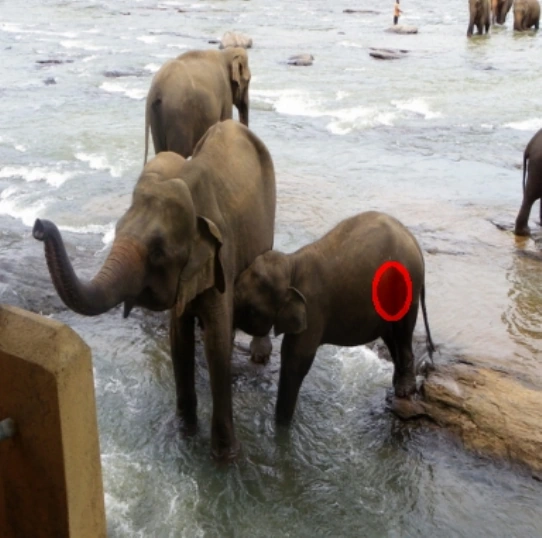
The support mask restricted to the elephant’s back
support mask, restricted
The prediction after the support mask is restricted
the prediction after
  1. The attribution taken over the prediction rests on the elephant's face and back.
  2. The attribution taken over the ground truth rests on the back alone.
  3. The difference points at the query, where the elephant's face is occluded. The face is in the support mask but has nothing to match, and those unmatched features are what the zebras pick up.
  4. Restricting the support mask to the back, circled in red, removes most of the zebra false positives and keeps the elephant.

No retraining and no gradient: reading the support set differently was enough to find the cause and act on it.

Causal Evaluation Metrics

To evaluate the faithfulness of our explanations, we extend Insertion AUC (IAUC) and Deletion AUC (DAUC) to FSS.

DAUC measures the drop in model performance (mIoU or Confidence) as we progressively remove the "most important" pixels from the support set. A good explanation method should cause a rapid drop. Conversely, IAUC measures performance gain as we introduce important pixels to an empty support set. We also introduce mIoULoss@p, which quantifies the accuracy loss when using only the top p% of relevant pixels.


Interactive Causal Analysis

Use the slider to observe the effect of perturbing the support set.

Query Analysis

Prediction
Segmentation
Uncertainty
Heatmap

1 (Start)
24 (End)

Perturbed Support Set

Shots 1 - 5

Quantitative Benchmark

mIoULoss@$p$ is how much segmentation quality is lost when the support set is reduced to the top $p$ of the pixels an attribution ranks highest: the lower, the more of the prediction those few pixels carry. Results are on COCO-20i and Pascal-5i in the 1-way setting, for four models spanning classical matching and recent pipelines built on vision foundation models. Best in bold, second best underlined. See the paper for the insertion and deletion curves and the remaining architectures.

Method 1-shot 5-shot
mIoULoss
@1% ↓
mIoULoss
@5% ↓
mIoULoss
@1% ↓
mIoULoss
@5% ↓
DCAMA
Random33.7929.7841.4231.62
Gaussian Noise Mask27.0712.9631.0817.71
Saliency33.9324.1337.0123.73
Integrated Gradients32.1922.6134.1822.25
Guided IG25.9619.4930.1721.65
Blur IG33.8923.2936.6922.84
XRAI29.6514.5026.5912.08
Deep Lift32.6024.8536.6724.07
LIME27.2713.4432.4415.29
Unmasked AffEx19.8410.0817.418.85
AffEx17.197.6415.389.83
DMTNet
Random23.5326.0124.9331.88
Gaussian Noise Mask16.208.6620.6913.26
Saliency20.1517.4621.0515.77
Integrated Gradients20.5320.8121.6320.32
Blur IG20.2217.4221.5420.20
XRAI14.836.3016.4810.73
LIME14.848.3219.2011.36
Unmasked AffEx10.974.1410.534.49
AffEx10.543.9010.354.09
INSID3
Random59.0846.6764.7863.71
Gaussian Noise Mask36.6212.6457.4626.31
LIME44.2922.0262.3152.01
Unmasked AffEx26.864.1828.617.13
AffEx23.793.0525.906.28
SANSA
Random64.5458.8768.5063.42
Gaussian Noise Mask41.0917.4853.5915.90
Saliency50.7728.2346.6917.16
Integrated Gradients52.8530.3849.1922.79
Guided IG41.7727.3731.8516.47
Blur IG52.7926.1748.5616.45
XRAI41.6313.7621.213.83
LIME50.9432.6264.2845.05
Unmasked AffEx35.6213.7218.214.59
AffEx29.267.4815.993.18

BibTeX

@inproceedings{demarinis2026affex,
  title={Matching-Based Few-Shot Semantic Segmentation Models Are Interpretable by Design},
  author={De Marinis, Pasquale and Kaymak, Uzay and Brussee, Rogier and Vessio, Gennaro and Castellano, Giovanna},
  booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
  year={2026}
}